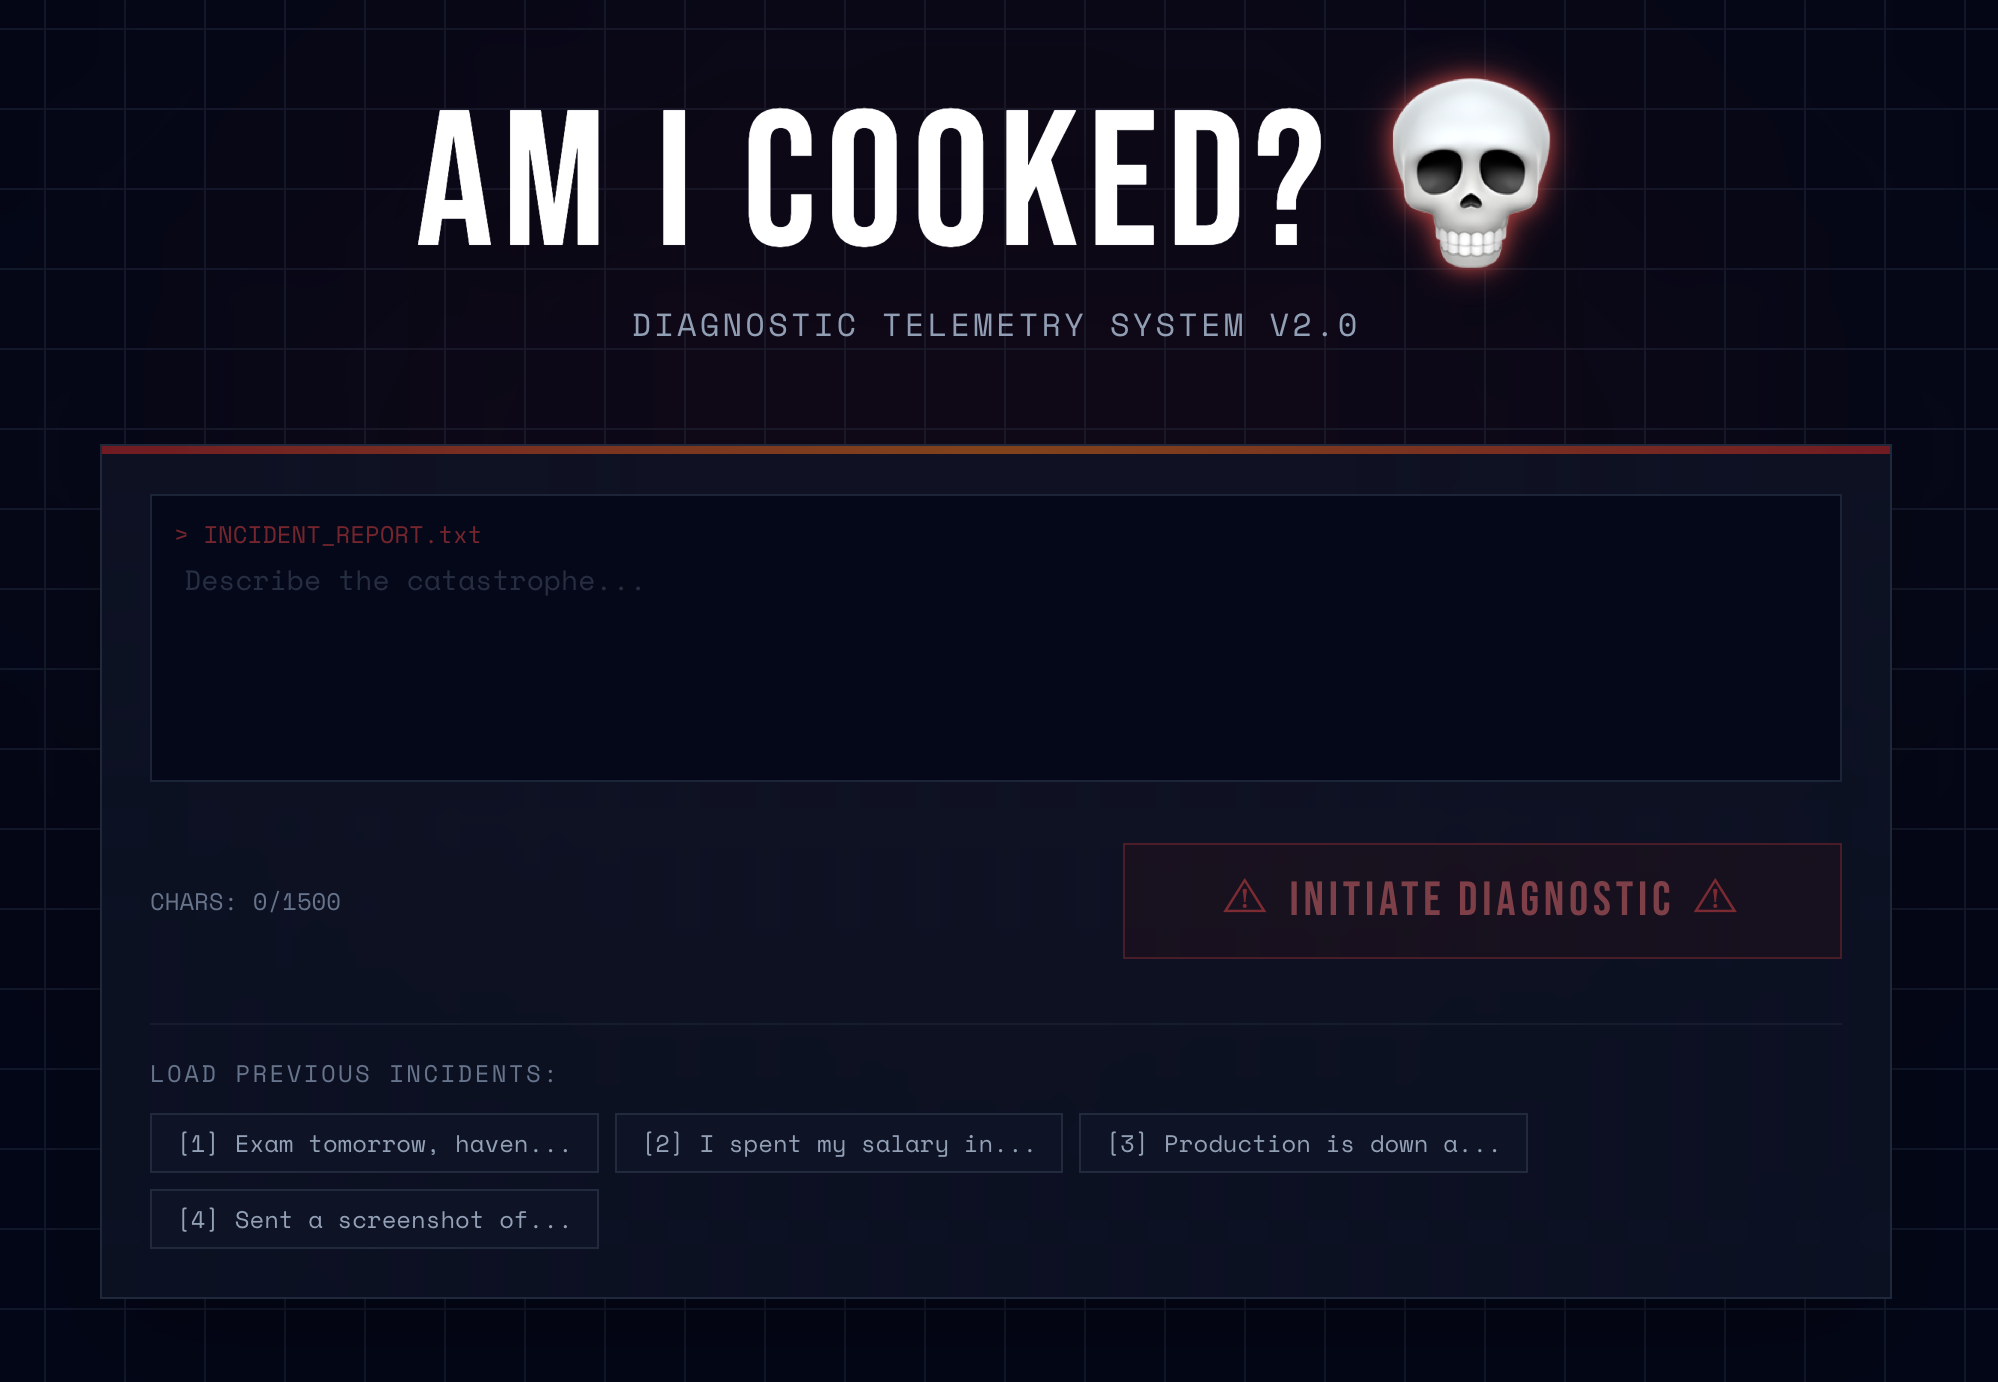
Am I Cooked? 💀
Tell an AI what happened. Let it decide how screwed you are.
* Note: This interactive widget is a static UI showcase. The actual Qwen3 4B inference engine is not running in your browser.
Okay, but there's actual AI underneath this.
The project uses a local Qwen3 4B model running on Apple Silicon, but rather than letting the LLM generate a free-form output, it separates contextual extraction from deterministic scoring.
The Interface
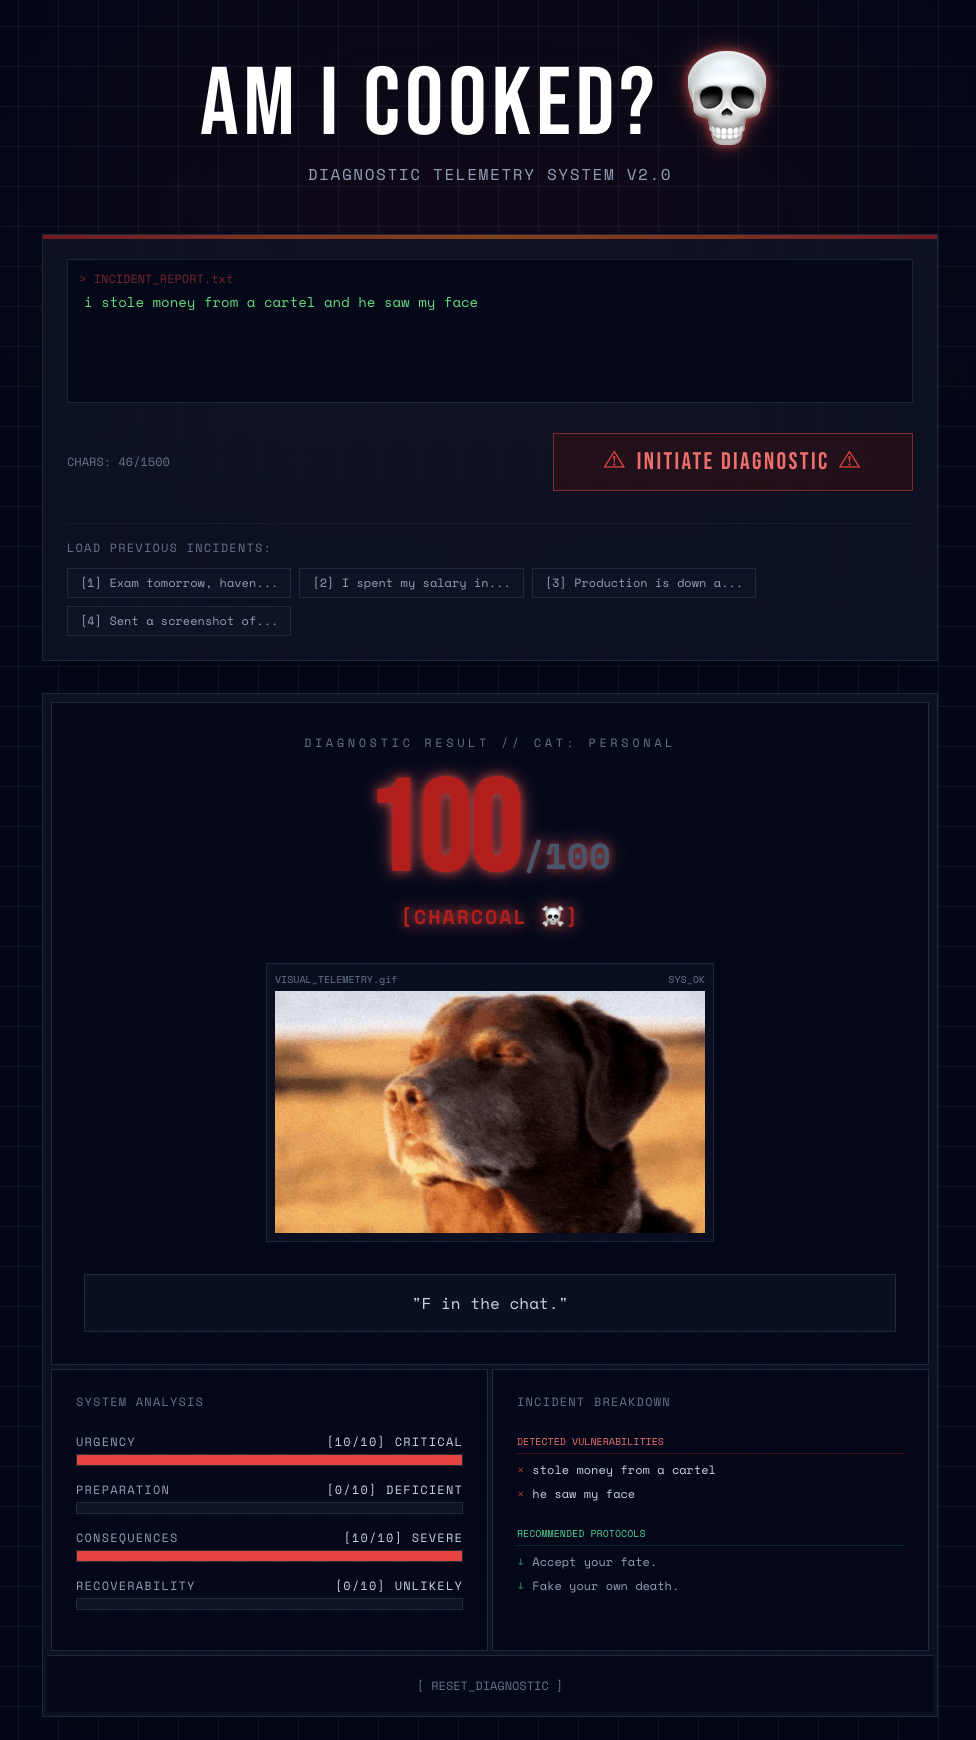
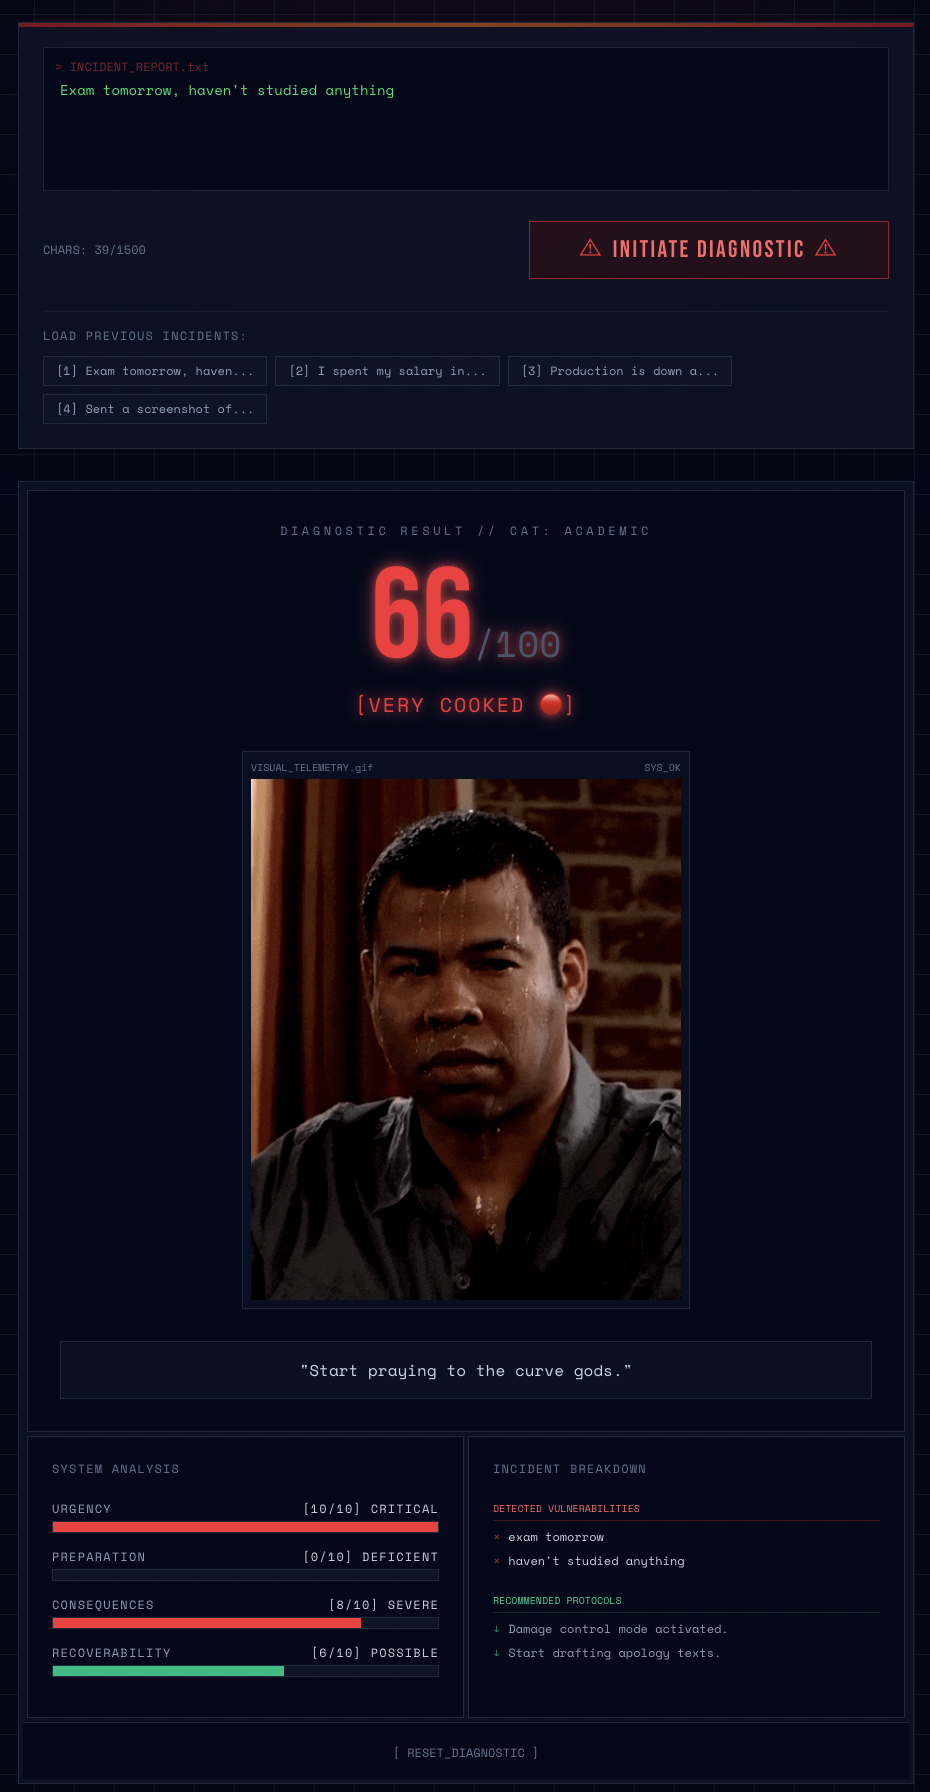
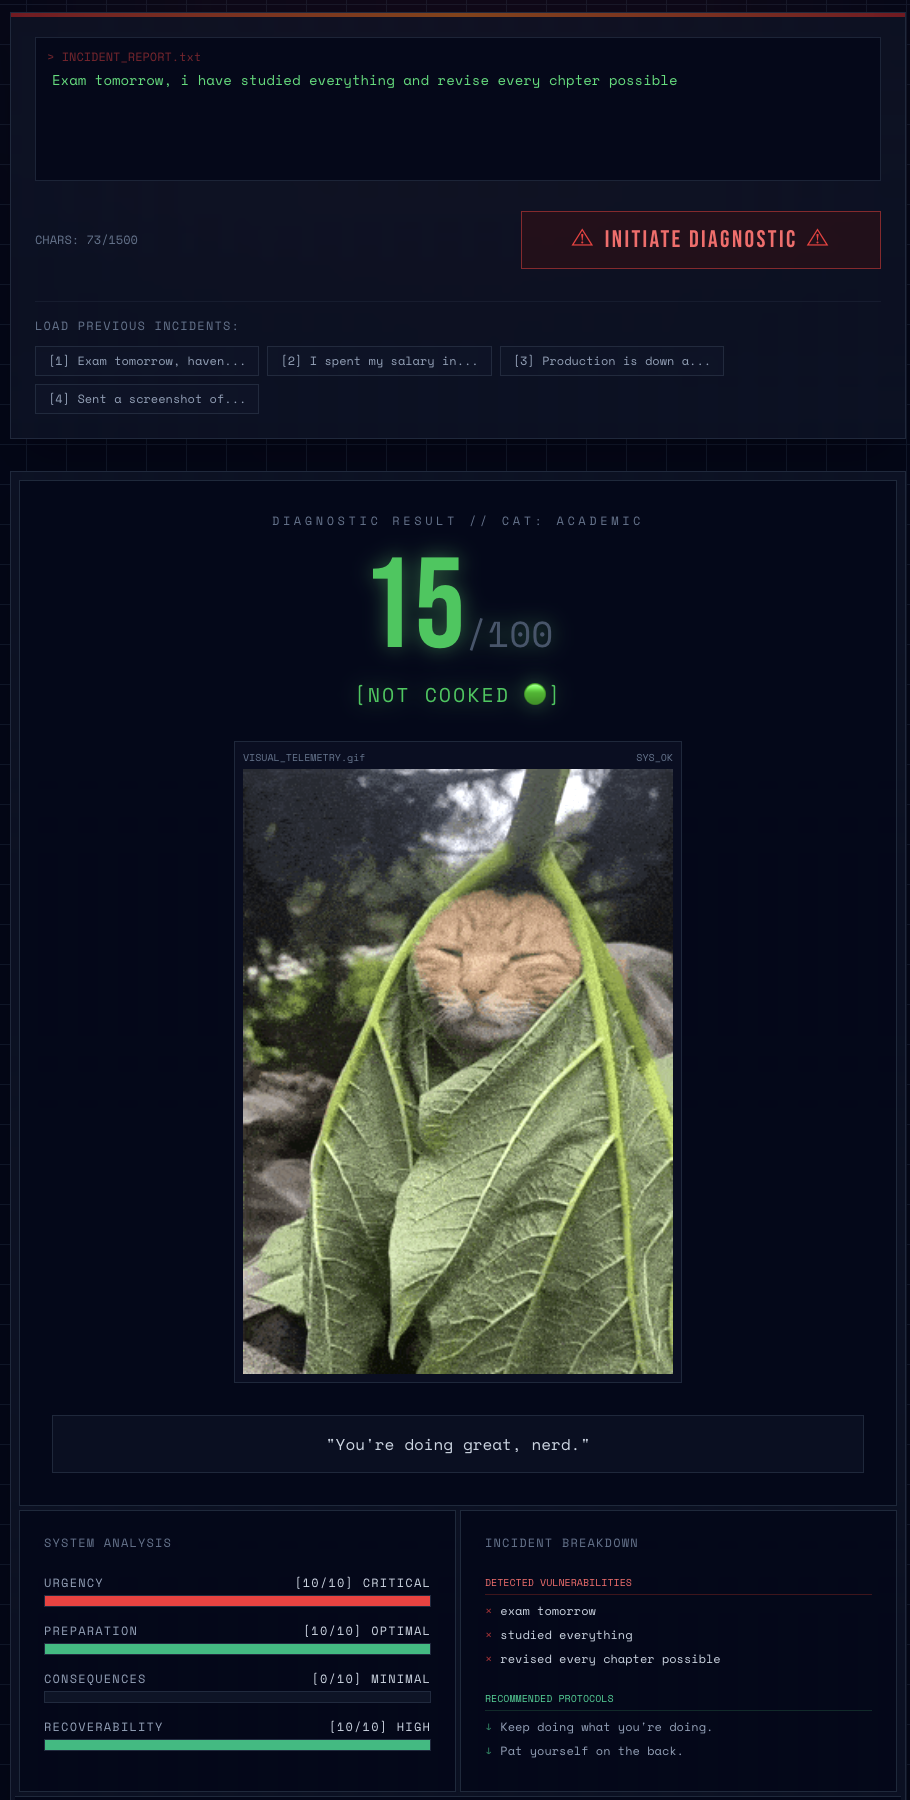
Why Not Just Classification?
The original baseline was a simple classification pipeline: Text → MiniLM → Logistic Regression → COOKED/NOT COOKED.
Problem: context matters. Two sentences can contain similar words while describing very different situations. It couldn't tell the difference between "I have an exam tomorrow and I've studied absolutely nothing" (Very Cooked) and "I have an exam tomorrow but I've studied 90% of the material" (Not Cooked). Both sentences have the same important words, but entirely different meanings.
Sarcasm broke it completely. The project therefore evolved toward contextual extraction with a local language model.
The Scoring Engine
The LLM doesn't decide your fate. Python does.
Your crisis never leaves your machine.
- ✓ Local Qwen3 4BIt judges you locally.
- ✓ Apple SiliconFast judgment. Unified memory.
- ✓ MLX / MLX-LMApple's native tensor framework.
- ✕ No cloud LLM dependencyOpenAI doesn't need to know about your 3.0 GPA.