Synthetic Data Analyzer
Generate synthetic tabular data, protect sensitive info, and measure how closely it preserves the original dataset.
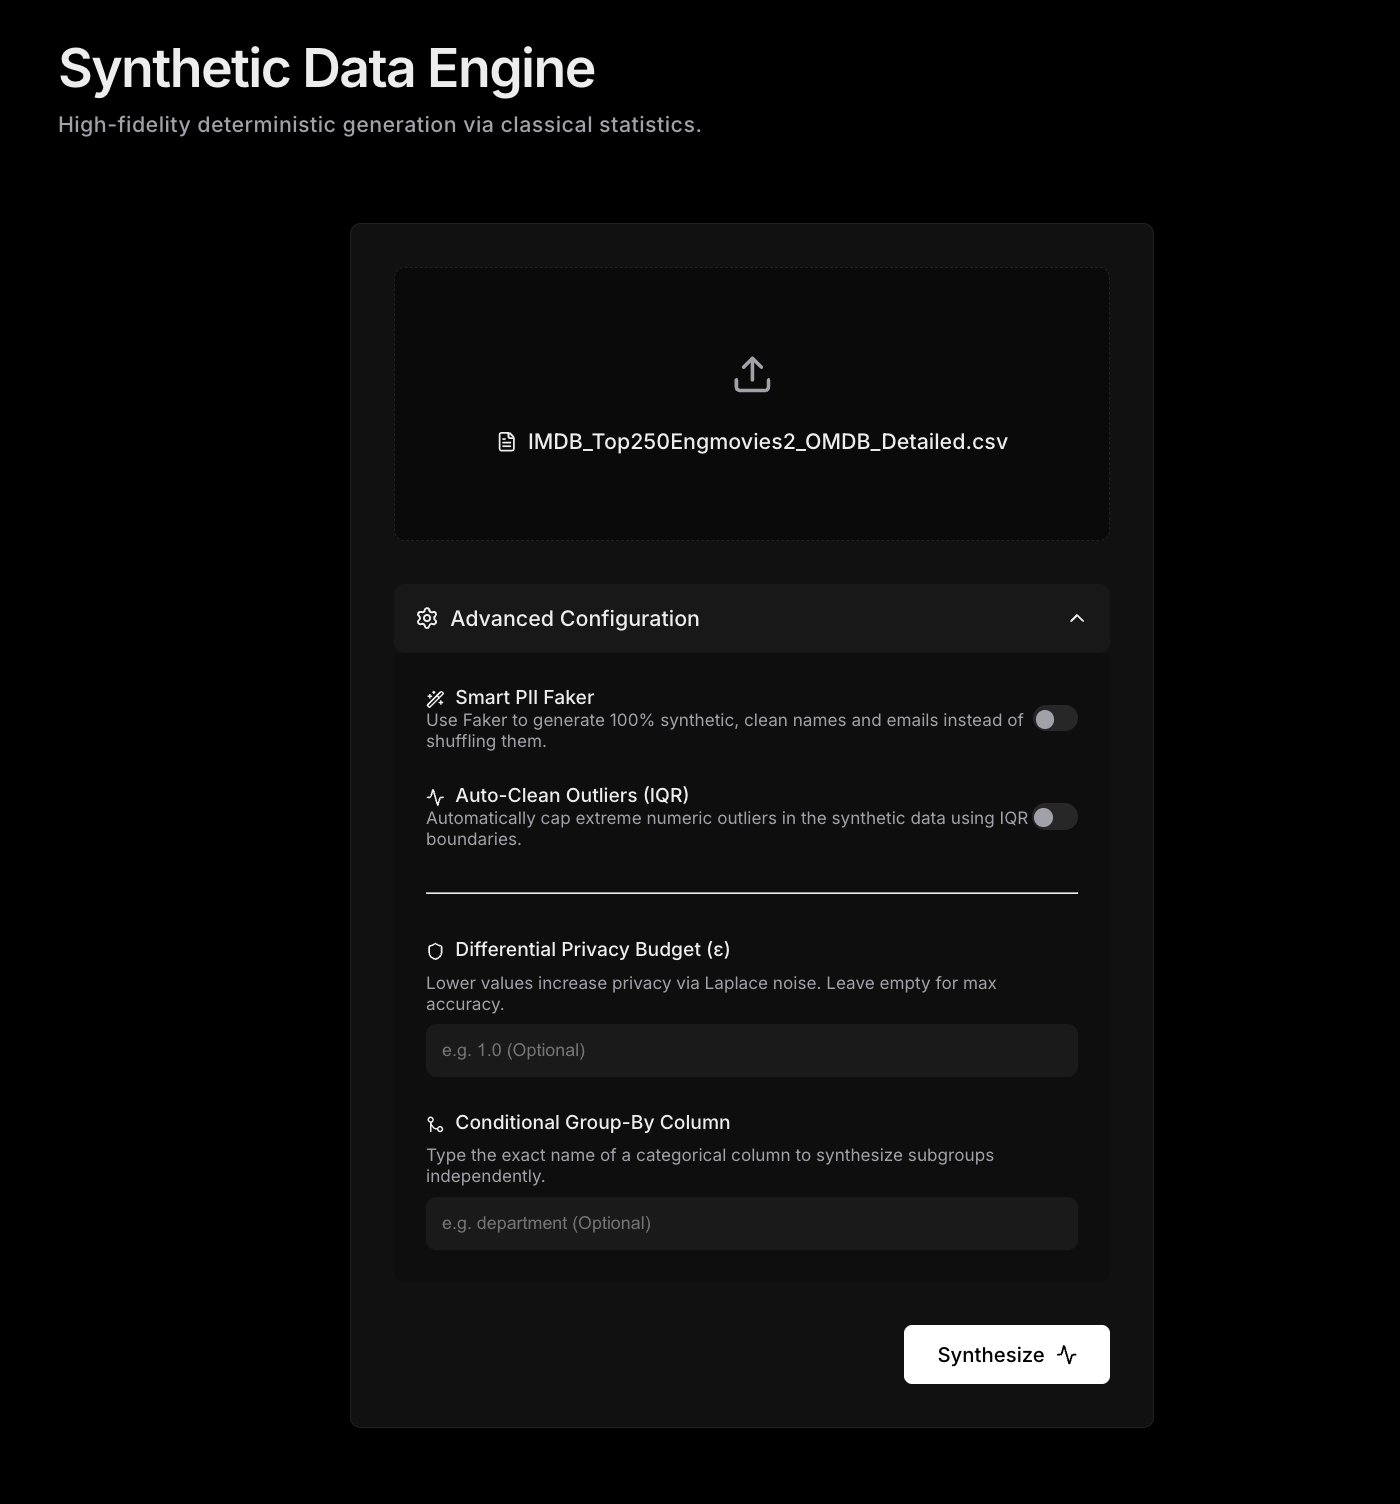
The Problem
Organizations often need realistic datasets for development, testing, analytics, demonstration, and research. However, directly sharing real datasets exposes sensitive Personally Identifiable Information (PII) and risks violating privacy regulations.
This project focuses on generating synthetic data that is completely structurally and statistically similar to the original dataset, without containing any of the original sensitive information.
Data Analysis
DATASET ANALYSIS
Synthetic Generation Pipeline
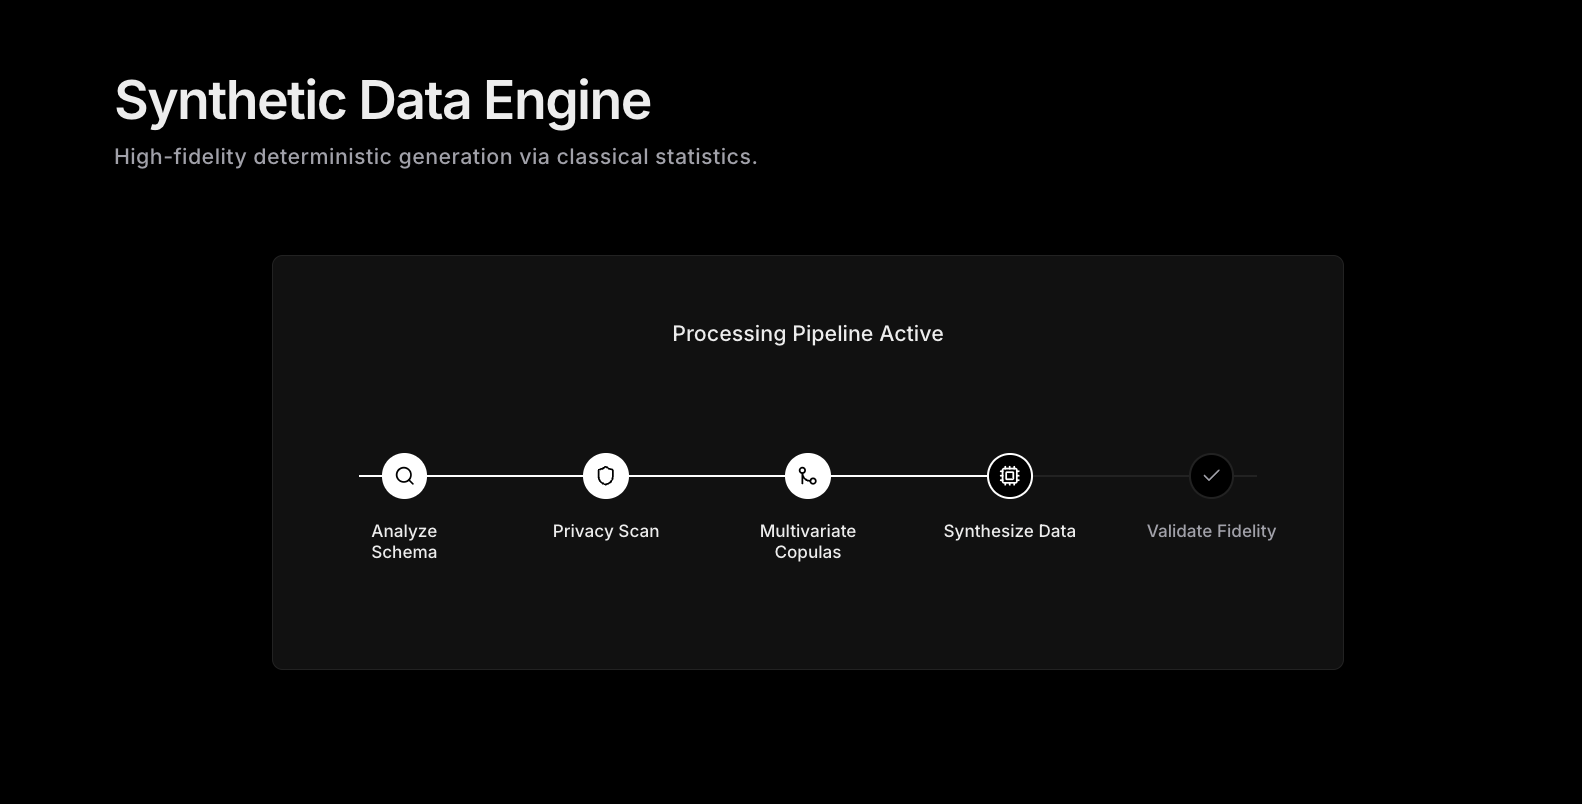
No ML. No LLMs. Pure Classical Statistics.
The project uses mathematically rigorous, deterministic algorithms to preserve utility and enforce privacy.
Differential Privacy (Laplace Mechanism)
Adds controlled mathematical noise to statistical parameters (mean, std) ensuring strong privacy guarantees (epsilon = 1.0) against reconstruction attacks.
Auto-Outlier IQR Cleaning
Automatically mitigates heavy skew and capping outliers using Interquartile Range (IQR) bounds during analysis.
Smart PII Semantics (Faker)
Automatically detects columns like `first_name`, `email`, and generates hyper-realistic fake semantic replacements rather than randomized text.
Primary Key Safety & Sub-schemas
Intelligently sequences unique identifier columns (`ID-1`, `ID-2`) and groups related data logically for unmatched realism.
Quality Validation
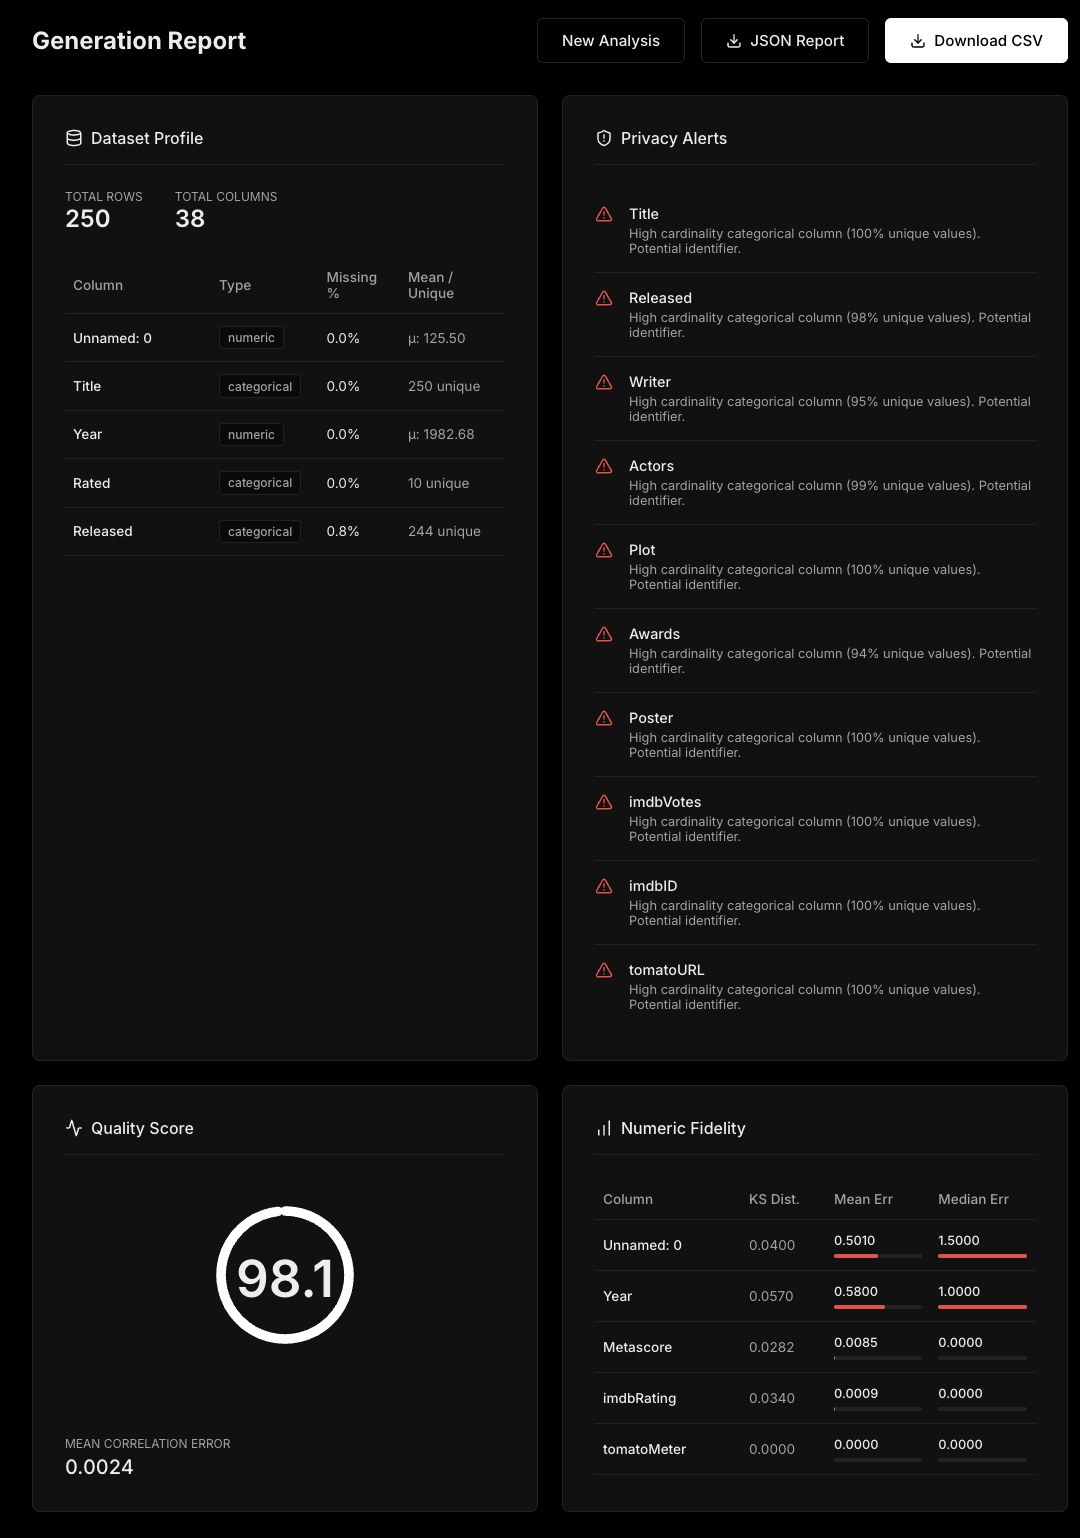
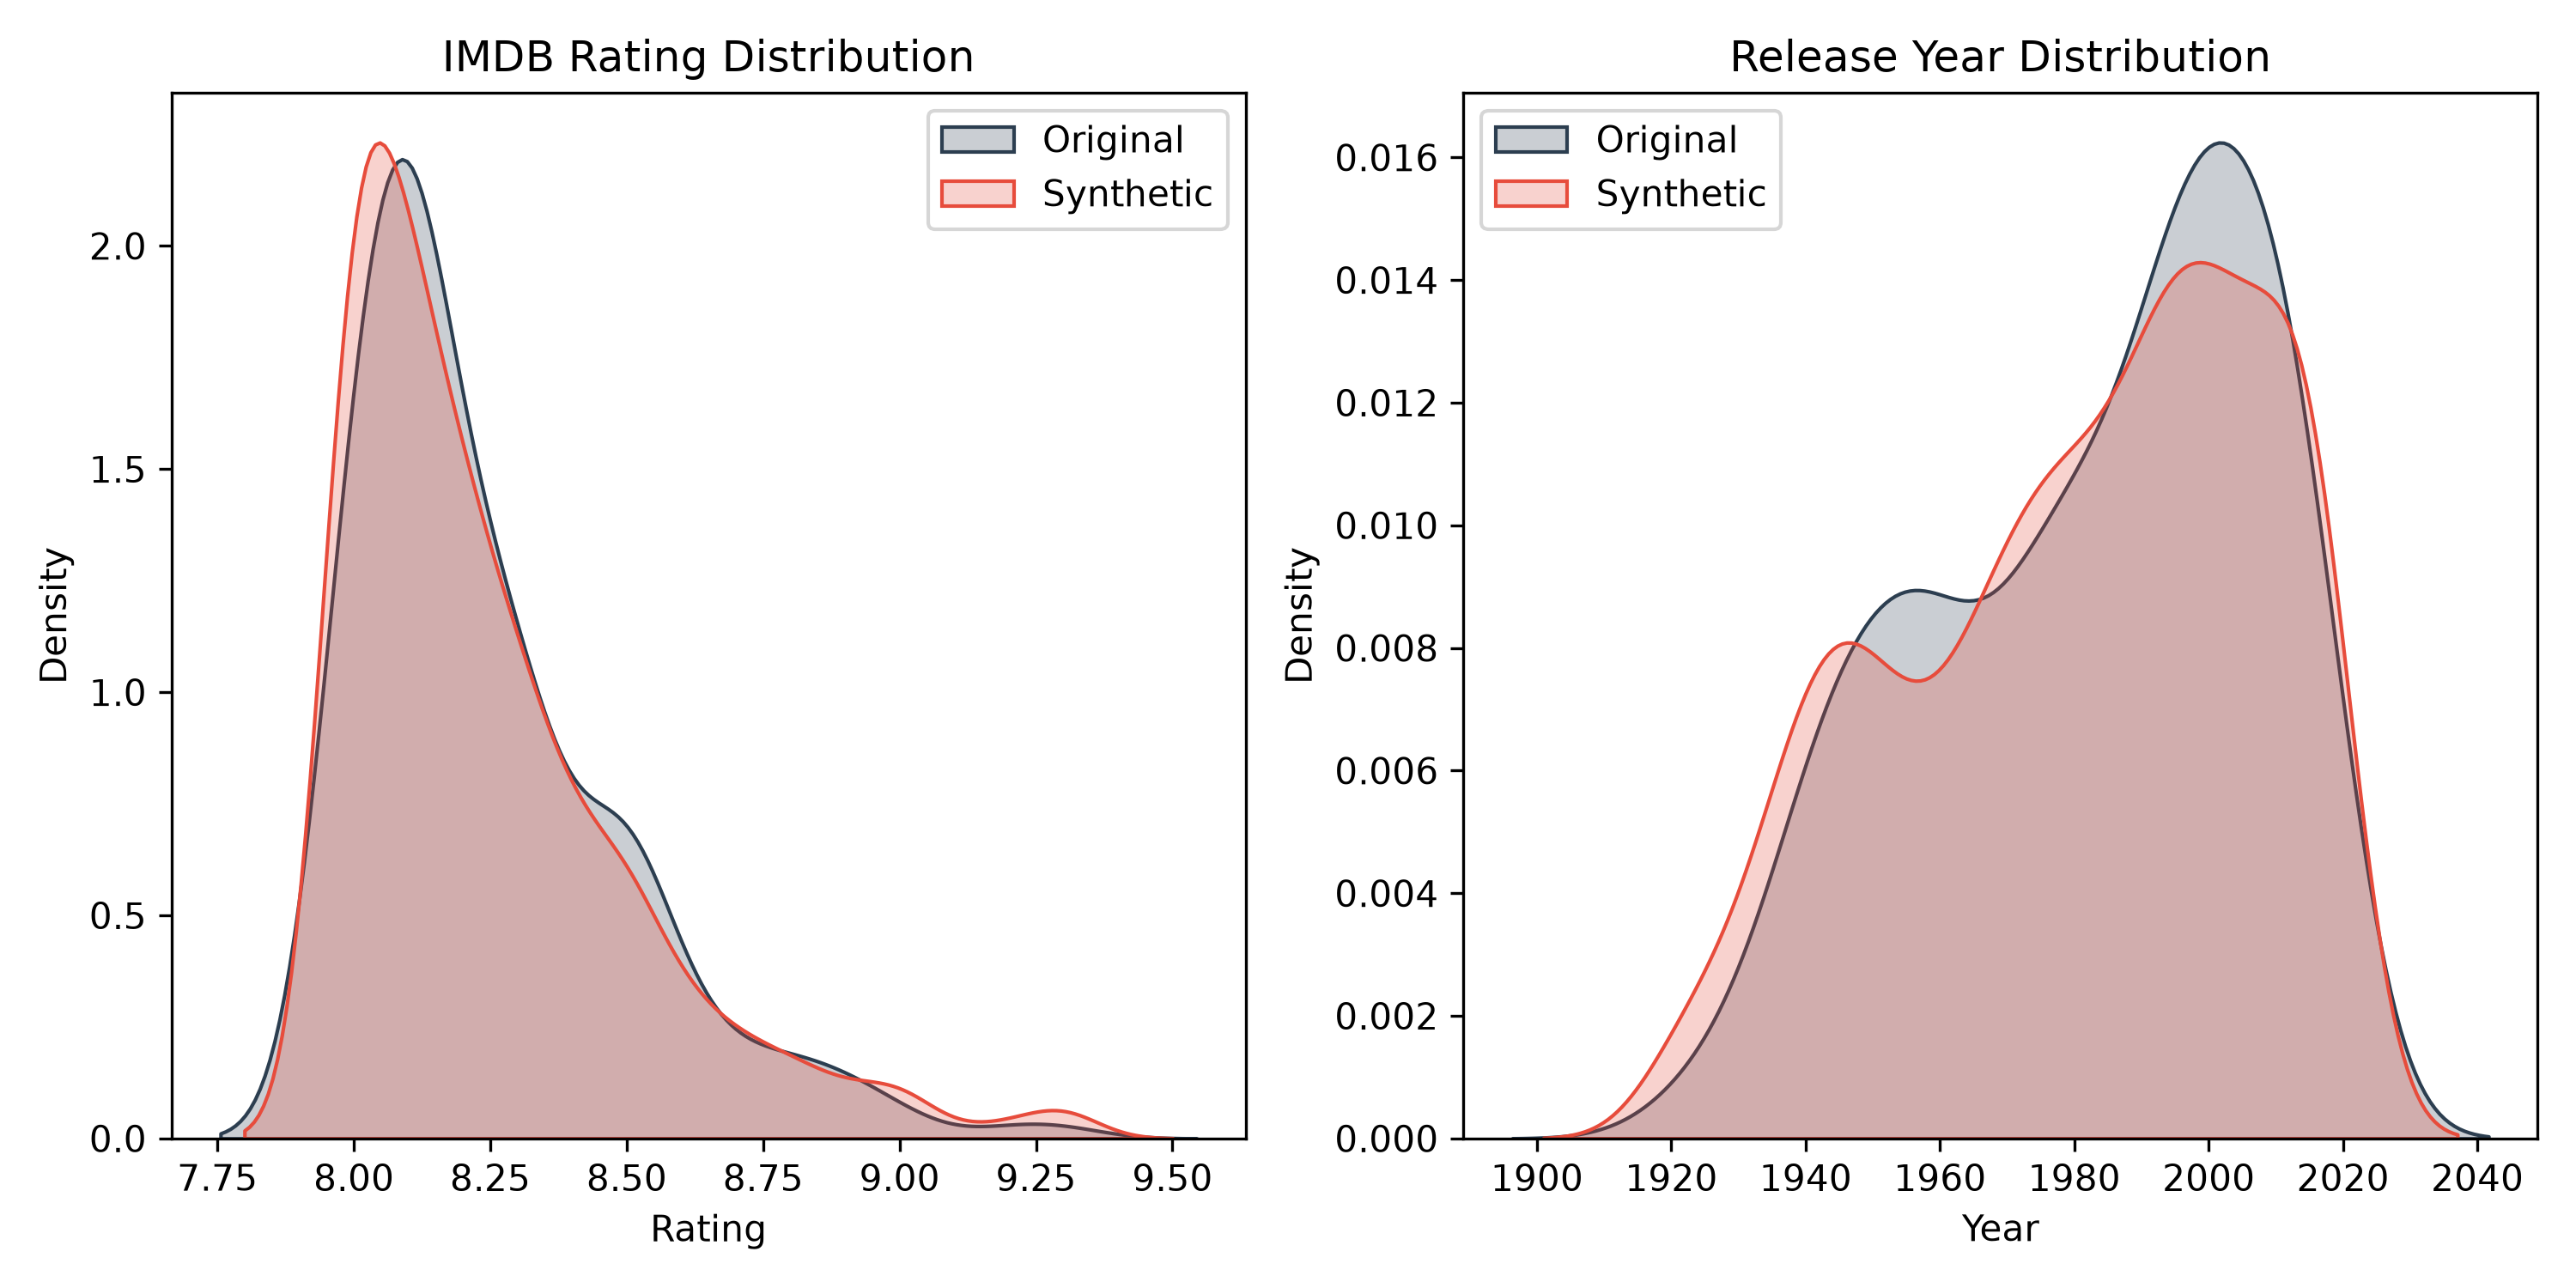
Preserving marginal distributions (shape) via KS-Test.
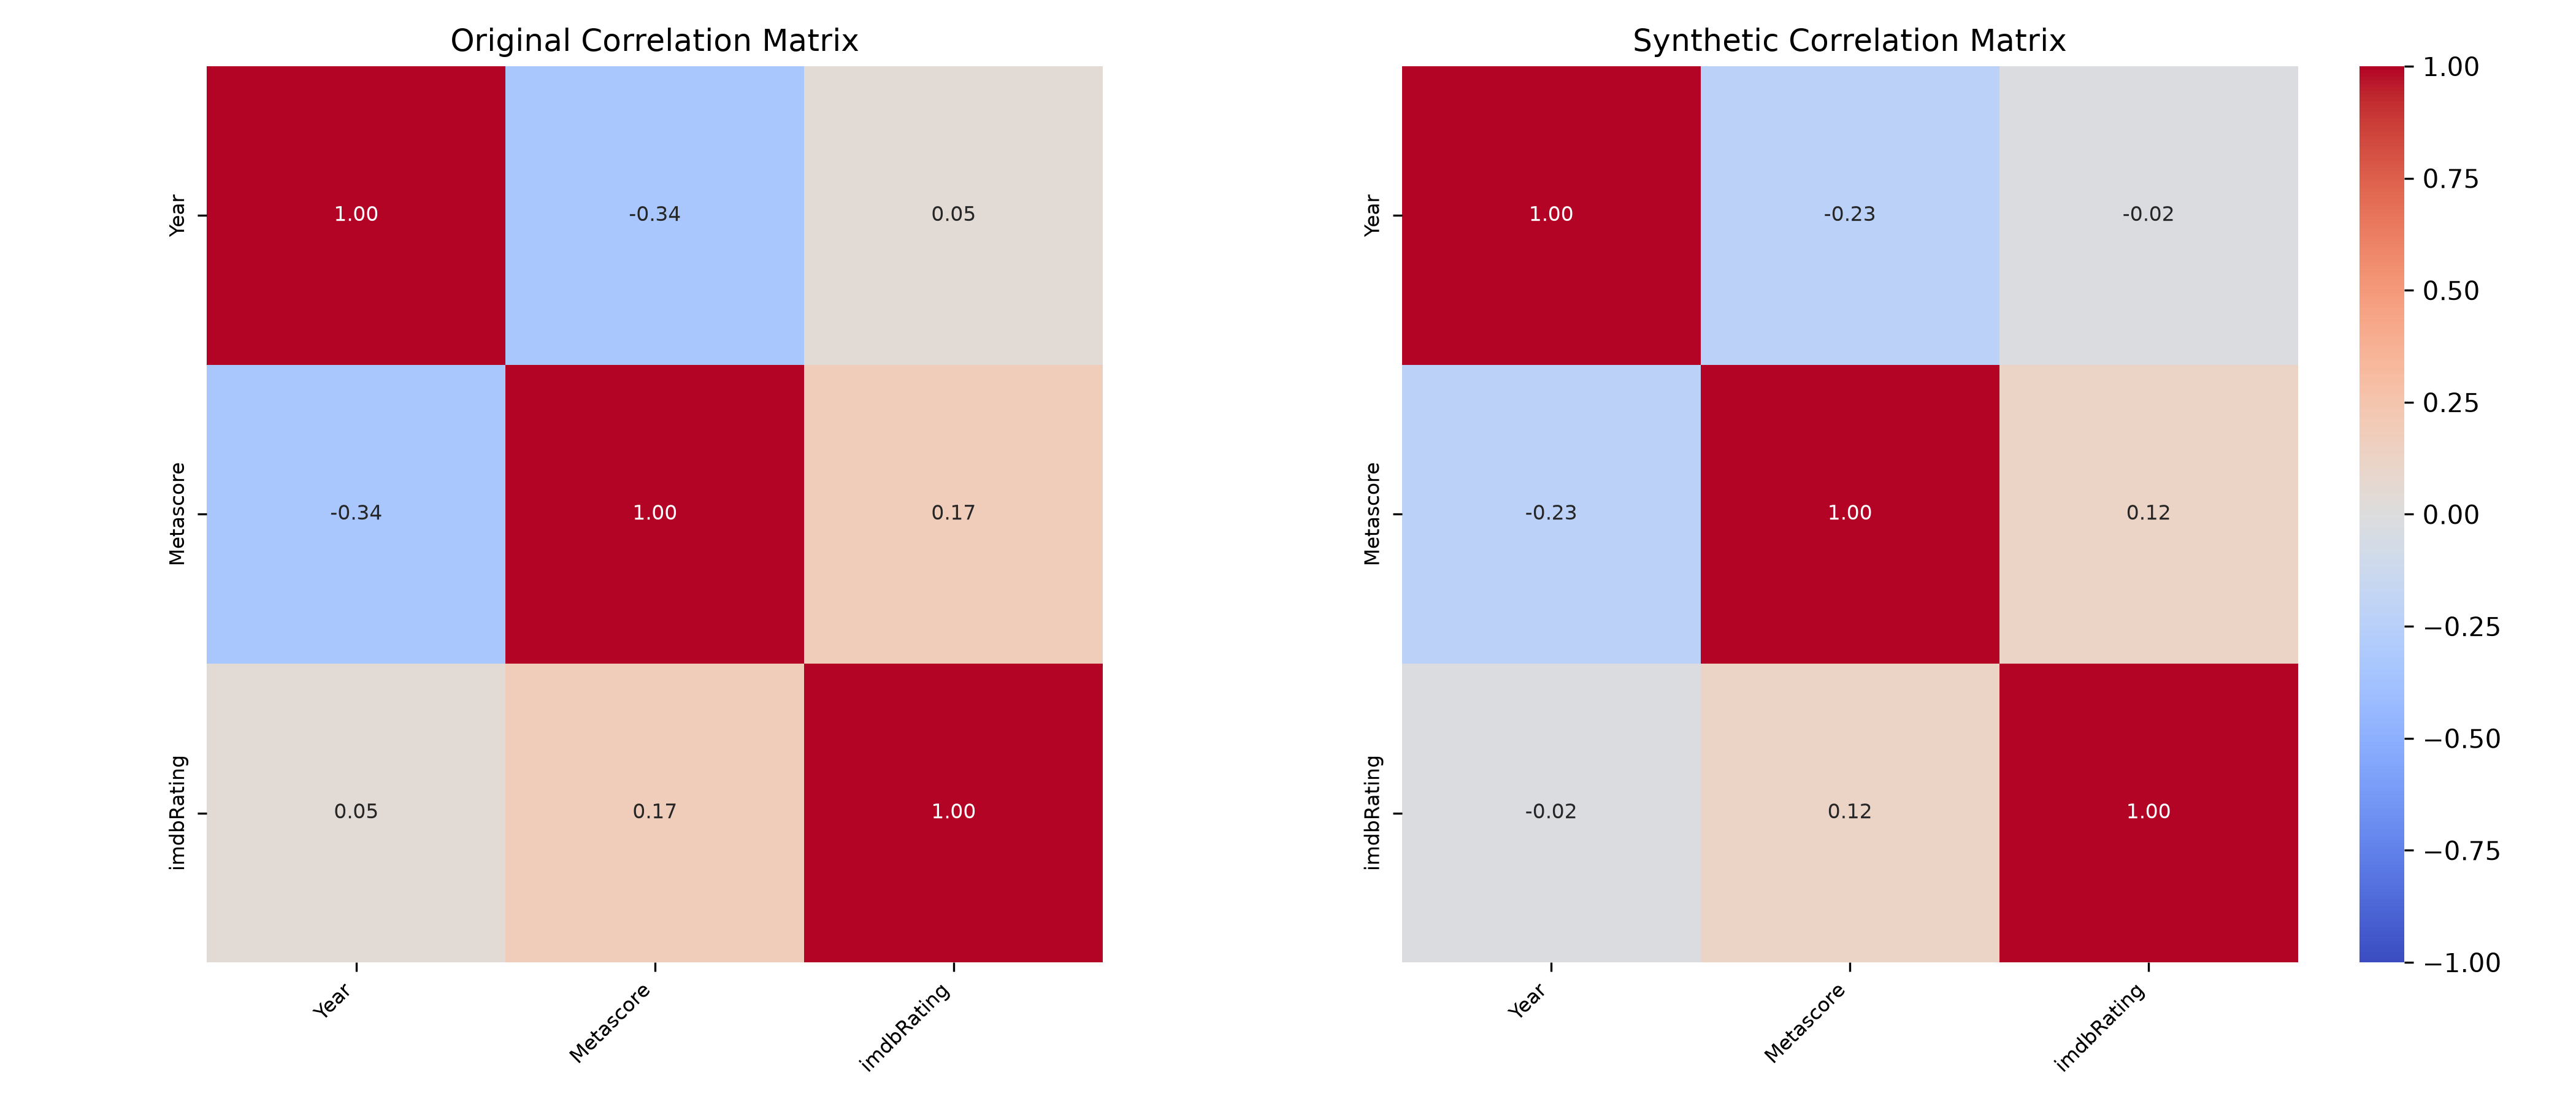
Preserving feature correlations via Gaussian Copulas.